Infra as a Service

Handle traffic spikes without downtime and scale in minutes
Keep your services online during planned peaks and unexpected growth. Place a managed Load Balancer before an on-demand Compute Instance fleet, then expand capacity without redesigning your application first. 
Domain names illustration

Distinguish genuine demand from attacks before scaling
Read the story behind every sudden traffic spike. Request rate, CPU, latency, and traffic shape provide the technical depth needed to detect real users, faults, or hostile activity. To handle traffic spike without downtime, distribute incoming traffic, add capacity, use caching, and apply database optimization. Anti-DDoS protection tackles malicious flows. This understanding helps manage traffic spikes, prevent website downtime under high traffic, and avoid crashes or a needless crash from inappropriate scaling.
[object Object]

Measurable safeguards for traffic surges

Get 99.99% SLA Compute and Load Balancing, plus Anti-DDoS protection up to 10 Tbps
99.99% SLA service commitment
99.99% service commitment
Anti-DDoS mitigation protection
Included mitigation
Load capacity limits
Published load limits

Build resilience across routing, compute, and data

Keep requests moving at the entry point

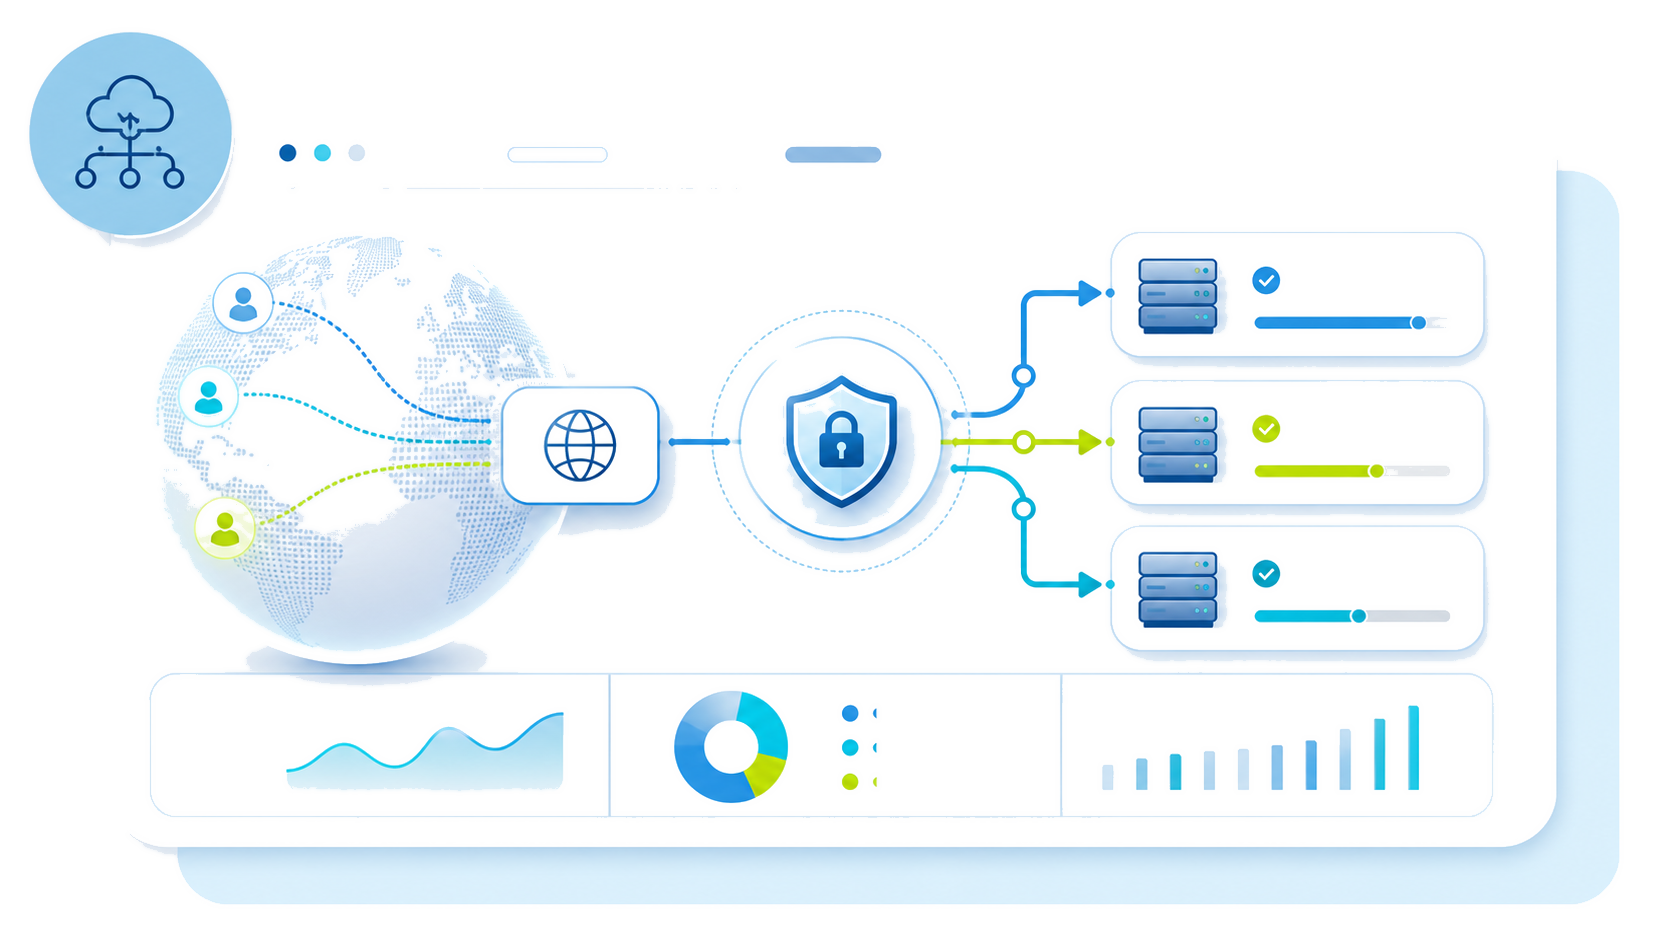
The managed Load Balancer checks backend health, terminates TLS, and uses weighted routing to control request delivery. If a server becomes unhealthy, automatic failover redirects users to available nodes.

Match compute capacity to observed demand

Scale a fleet of identical Gen3 Compute Instances behind the routing layer. Choose capacity from measured traffic patterns rather than assumptions, then add nodes in a controlled step as demand grows. Where a company requires geographic resilience, deploy across three availability zones in Paris or Milan.

Protect the database from displaced load

Additional front-end capacity can expose a database constraint instead of resolving it. Protect connection pools, cache suitable accessed data in memory, and inspect slow search or checkout queries before scaling further. These checks identify potential bottlenecks that extra application nodes cannot remove. DDoS protection addresses hostile web traffic, while this layered architecture handles legitimate spikes.

Preserve a stable service address through every change

OpenStack OctaviaFloating IPTLS
OpenStack Octavia routes requests to healthy backends, terminates TLS, and uses weighted distribution to prevent one VM becoming the entry-point constraint. A Floating IP preserves the public address while teams replace, resize, or fail over resources within the required time frame.

Select options based on traffic measurements, then test performance under flash-sale and media-event conditions. These strategies help handle traffic spike without downtime and protect the user experience throughout the scaling window.
[object Object]
A known launch date gives teams time to test the complete configuration under representative heavy demand. Create temporary Compute Instances from a reusable golden image, validate customer journeys, and use weighted load balancing to introduce capacity before visitors arrive. This strategy is effective for seasonal commerce, ticket releases, and scheduled media coverage. Because the additional infrastructure is temporary, the company avoids paying for unused static headroom during quieter periods.

Sudden attention requires a fast, measured response. Scale Compute Instances on demand, validate each new node, and distribute incoming traffic across multiple healthy servers. Apply rate limiting where a scarce downstream resource, such as authentication, inventory, or payment processing, needs protection. Do not expand every dependency automatically: read latency and error indicators to determine where the constraint sits.

High-availability hosting requires protection from both demand shifts and location failure. A Multi-AZ architecture reduces reliance on one availability zone, while static capacity provides immediate headroom for common fluctuations. Teams can then add resources rapidly when conditions exceed that baseline. After traffic normalises, confirm that queues, latency, and errors remain stable before removing temporary nodes.
A known launch date gives teams time to test the complete configuration under representative heavy demand. Create temporary Compute Instances from a reusable golden image, validate customer journeys, and use weighted load balancing to introduce capacity before visitors arrive. This strategy is effective for seasonal commerce, ticket releases, and scheduled media coverage. Because the additional infrastructure is temporary, the company avoids paying for unused static headroom during quieter periods.

Make every surge response repeatable

Capacity baseline

Load-test major user journeys and record where compute, network, or database performance becomes overloaded. This baseline supports a realistic plan based on current demand.

Reusable build

Maintain a tested instance snapshot or golden image. Every new node can then share the same application, security, and network configuration.

Operational visibility

Implement monitoring before an event for request volume, latency, errors, CPU, connections, and frequently accessed data. Alerts help teams respond faster to unexpected demand.

Scaling maturity

Use scripted VM expansion to handle traffic spikes or a social-driven surge.

Roll out surge protection through four workstreams

Baseline and protect

Quantify expected and sudden traffic, define service objectives, and load-test critical paths. Confirm that attack mitigation is active so teams can handle increased demand without confusing hostile activity with legitimate growth.

Build and automate

Describe the fleet, network, and balancing configuration with Terraform. Repeatable infrastructure code helps engineers add capacity consistently within minutes or hours, instead of rebuilding servers manually during an incident.

Validate data and experience

Test database connections, error rates, and load times under increased traffic. Include node and zone failures to confirm that the architecture maintains a smooth user experience when individual components become unavailable.

Operate and recover

Document scaling triggers, approval and contact paths, rollback guidance, and ownership. Define when temporary capacity is safe to remove after a viral moment, based on stable service health rather than the first fall in traffic.

Remove temporary capacity when performance stabilises
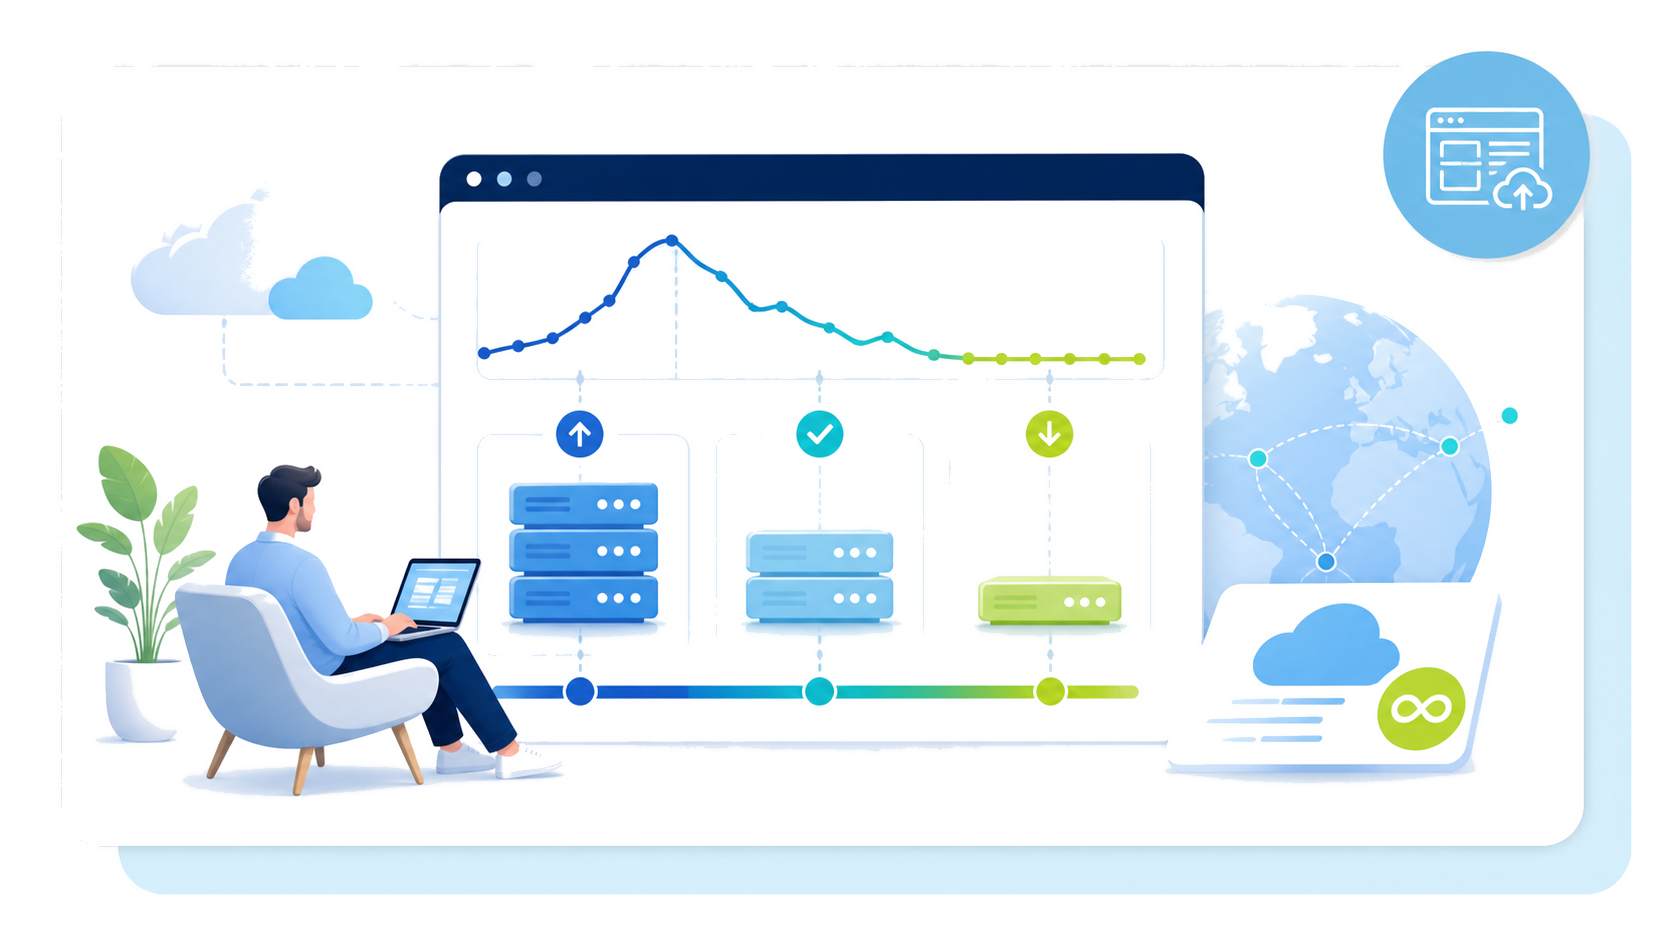
Per-second billing for Compute Instances, with a 60-second minimum from May 2026, aligns temporary capacity with each spike. Observe when application demand returns to normal, the request queue drains, and service speed stabilises before removing surplus nodes efficiently. This measured approach helps ensure cost control without risking crashes. Unlimited unmetered egress in most regions can reduce unnecessary uncertainty for content-heavy cloud hosting; verify regional availability and terms for your business.
[object Object]
Prepare your infrastructure before the next surge
Start a Public Cloud trial or activate a managed Load Balancer. Deploy, test, and refine your response before demand rises.
Activate Load Balancer