AI Deploy
Serve your AI model as an API on dedicated GPUs, from your container. Autoscaling down to zero for your metrics, charged by the minute.
Serve your models without managing infrastructure

No servers to manage
OVHcloud manages servers, endpoints, autoscaling and Grafana. You manage your images and models.
Quick start
Drivers and CUDA ready to go: only your image and your model are loaded when you get started.
Custom autoscaling
Scale based on your own metrics. Without traffic, the app stops and is no longer billed. Grafana included.
Compliant and secure
ISO 27001, SOC 2 Type II, HDS (EU regions). Ensures the sovereignty of your data.
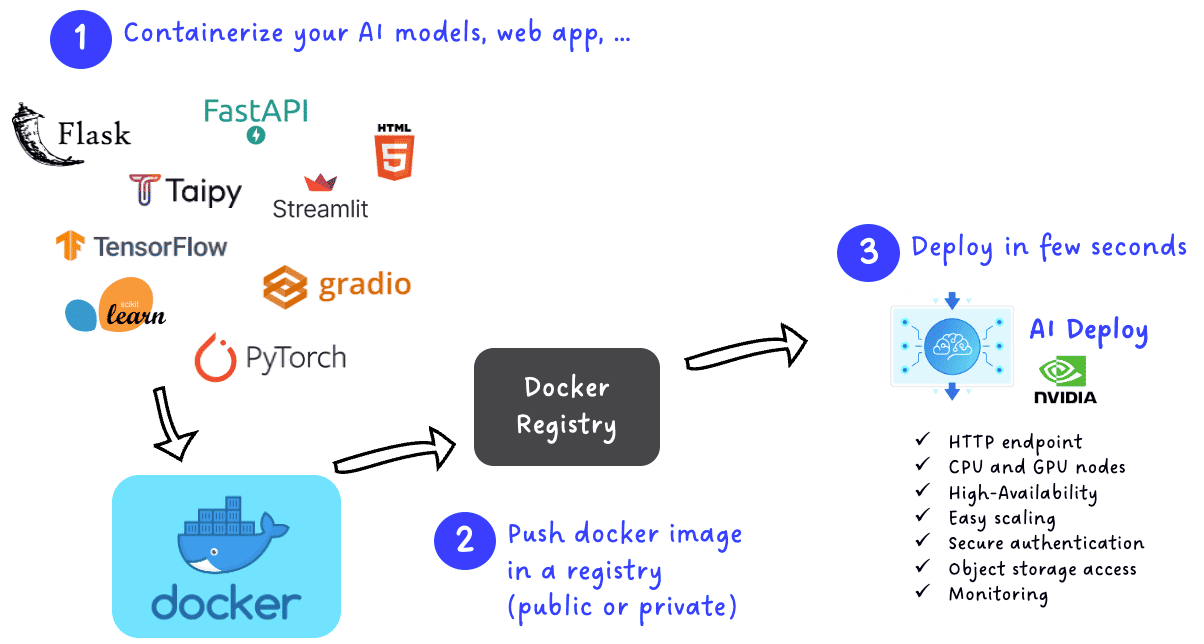
Your model live in 3 steps
1. Select your image
Deployment of an inference server, an API or an app.
2. Set GPU and scaling
The GPU, then autoscaling on your metric, from 0 replicas.
3. Call your endpoint
An HTTPS URL protected by token or by username and password.
Deployment of an inference server, an API or an app.
2. Set GPU and scaling
The GPU, then autoscaling on your metric, from 0 replicas.
3. Call your endpoint
An HTTPS URL protected by token or by username and password.
Everything to serve a model in production

Autoscaling rules
CPU, RAM or custom metric, adjustable delay before resetting to zero.
High availability
Load balancing managed by OVHcloud, replicas recreated automatically.
Disruption-free updates
New image deployed without downtime, on the same URL.
Grafana monitoring
CPU, GPU and RAM metrics per app, without configuration.
Secure access
Endpoint protected by token or password.Object Storage volumes
Your weights loaded from a bucket, not from the image.Console, API or CLI
From the customer control panel, the API, the CLI or the Python SDK.Images from your registry
From Docker Hub, GitHub or Managed Private Registry.
Use case examples
Three ways to serve your models with AI Deploy, each with a guide to get started.

Your fine-tuned LLM
Have you adapted an open-weight model to your business? Serve it behind vLLM, callable by any OpenAI-compatible tool.
RAG chatbots and agents
Your assistant answers from your own documents: the app on AI Deploy, the vectors in pgvector, the LLM on AI Endpoints.
Internal tools and demos
Prototypes, demos and Streamlit apps for your teams, used a few hours a day and stopped the rest of the time.
AI Deploy: feedback
- Read the case study
lector.ai
500 M pages processed · 80% of processing time saved. Document processing for health insurers, after migration from a US cloud. - Read the case study
moinAI
Customer service chatbots: moinAI trains its models on AI Training and serves them on AI Deploy.
AI Deploy or Cloud GPU?
Are you hesitating between AI Deploy and your own Cloud GPU instances for serving your models? Here's what changes.
OVHcloud AI Deploy | OVHcloud Cloud GPU | |
|---|---|---|
Type of service | Managed container (CaaS) | GPU instance to manage (IaaS) |
No traffic | Automatic shutdown, €0 | Billed even when switched off |
VM, drivers and CUDA | Already ready | To be installed and maintained |
Startup | Image loading only | Boot VM, GPU stack, CUDA, then image |
HTTPS endpoint and autoscaling | Included | To be built |
GPU monitoring | Grafana included | To be configured |
L40S GPU price | €1.55 ex. VAT/hour | €1.40 ex. VAT/hour |
Perfect for | Variable traffic, team without MLOps | Stable load 24/7, full control |
A stopped or paused instance remains billed at the same rate; only manual shelving reduces the bill to the snapshot.
Choose the GPUs used for your AI Deploy service
Hourly price, billed by the minute. Traffic included, no commitment.
See all Public Cloud pricesL4
Small models, embeddings€0.83ex. VAT/hour
- NVIDIA L4, 24 GB
- 1 to 8 GPUs per replica
- Gravelines (France)
L40S
Fine-tuned LLMs, images€1.55ex. VAT/hour
- NVIDIA L40S, 48 GB
- 1 to 8 GPUs per replica
- Gravelines (France)
A100
LLMs and vision, large batches€3ex. VAT/hour
- NVIDIA A100, 80 GB
- 1 to 8 GPUs per replica
- Gravelines (France)
H100
Large LLMs, high throughput€3.10ex. VAT/hour
- NVIDIA H100, 80 GB
- 1 to 8 GPUs per replica
- Gravelines (France)
H200
Very large LLMs, multi-GPU€23.12ex. VAT/hour
- 4 × NVIDIA H200, 141 GB
- NVLink between the 4 GPUs
A10
Compact models, NLP€0.90ex. VAT/hour
- NVIDIA A10, 24 GB
- Gravelines (France)
V100S
Also available in Canada€1.93ex. VAT/hour
- NVIDIA V100S, 32 GB
- GRA and BHS
CPU
Lightweight apps, classic ML€0.03ex. VAT/hour/vCore
- Up to 12 vCores per replica
- GRA and BHS
Prices as of 14/10/2026. Storage billed separately.
SPECIFICATIONS
Technical specifications

GPU
H200, H100, A100, L40S, L4, A10, V100S
Resources per replica
Up to 8 dedicated GPUs or 12 vCores

Scaling
0 to 10 replicas, autoscaling included
Network
HTTPS or gRPC, traffic included

Regions
Gravelines (FR), Beauharnois (CA)Availability
99.95% SLA, HA from 2 replicas
Guides
- Find out more
Getting started with AI Deploy
Your first app, from image to URL. - Find out more
Configure scaling
Autoscaling and scaling to zero replicas. - Find out more
Monitor your app
Grafana metrics and your app logs.